Newton, Antigravity, and the Apple on the Wooden Table: Writing a Native FLUX.1 Engine in Lisp for Apple Silicon and AMD ROCm
In the late summer of 1665, a young Cambridge scholar named Isaac Newton fled the Great Plague of London to his family estate at Woolsthorpe Manor in Lincolnshire. Sitting in the orchard, so the legend goes, he watched an apple drop from a tree to the ground.
He didn’t ask what variety of apple it was. He asked a terrifyingly universal question: Why did it fall straight down to the center of the Earth, rather than sideways or upward? From that simple observation, he derived the inverse-square law of universal gravitation, unified terrestrial and celestial mechanics, and changed physics forever.
Fast-forward 361 years to the autumn of 2026.
We were sitting in front of two glowing workstations: a sleek MacBook Pro running Apple Silicon and an AMD APU workstation named monster running Linux and ROCm. We gave our systems a prompt:
“a red apple on a wooden table”
Only this time, we weren’t watching gravity pull matter downward. We were using Conigravity—our custom Lisp runtime and neural tensor engine—to pull 12 billion parameters across 3,072-dimensional latent vector spaces, guiding 512×512 Gaussian noise through 4 steps of flow-matching differential equations until a crisp, photorealistic red apple materialized on a polished grain table.
And the crowning glory?
Zero lines of Python. Zero PyTorch. Zero Diffusers. Zero CUDA conda environments. Zero ComfyUI.
Just a single standalone Lisp binary called coni, talking directly to bare metal on both Apple Metal (via MLX) and AMD ROCm (via native HIP C++ kernels).
Here is the wild, caffeine-fueled engineering saga of how we built an end-to-end, production-grade FLUX.1-schnell inference engine from scratch in a Lisp dialect, the harrowing battle with 8-bit floating point subnormals (FP8 E4M3FN), and the tale of two apples.
Act I: The Modern AI Dependency Circus
If you have ever tried to run modern generative diffusion models locally, you already know the trauma.
You clone a repository. You run pip install -r requirements.txt.
ERROR: Cannot install torch==2.4.0 because these package versions have conflicting dependencies:
  torchvision 0.19.0 depends on torch==2.4.1
  accelerate 0.33.0 requires huggingface-hub>=0.21.0
  triton requires python<3.12
You create a fresh Conda environment. You download 4.8 gigabytes of CUDA toolkits. You discover that your ROCm driver version is 6.2, but the PyTorch wheel was compiled for ROCm 6.1.5 against Ubuntu 22.04, whereas you are running Arch. You export HSA_OVERRIDE_GFX_VERSION=11.0.0. You run the script. It allocates 28 gigabytes of VRAM before crashing with an uncatchable CUDA Out of Memory error during the VAE decode step.
Meanwhile, your MacBook’s fans are screaming in agony because Python is busy copying 16-bit floating-point tensors back and forth across three distinct memory wrappers.
We asked ourselves the forbidden question:
Why are we running a 12-billion parameter linear algebra calculation through an interpreted scripting language created in 1991, wrapped in three C++ shims, seven abstraction frameworks, and a Python virtual environment larger than the Apollo 11 flight software archive?
What if a single, statically compiled 25MB executable—written in Coni, our fast Clojure-like Lisp in Go—could load raw HuggingFace GGUF and Safetensors weights directly from disk into GPU memory, orchestrate the entire diffusion pipeline in functional Lisp code, and generate images in seconds?
;; The entire user-facing generation pipeline in pure Coni Lisp
(ns generate-image
  (:require [coni.gguf.flux :as flux]
            [coni.image :as image]))

(defn -main [prompt output-path]
  (println "[Coni-Flux] Generating:" prompt)
  (let [img (flux/generate {:prompt prompt
                            :steps 4
                            :width 512
                            :height 512
                            :seed 42})]
    (image/save! img output-path)
    (println "[Coni-Flux] Saved to" output-path)))
To make this snippet a reality, however, we had to build an entire neural network compiler and runtime from the silicon up.
Act II: Dissecting the FLUX.1 Beast
Black Forest Labs’ FLUX.1-schnell is not your grandfather’s Stable Diffusion 1.5. It is a state-of-the-art Rectified Flow Matching Transformer containing over 12 billion active parameters.
Generating a single image requires orchestrating four massive neural network stages in strict mathematical harmony:
flowchart TD
    subgraph Stage1 ["Stage 1: Prompt Encoding (Dual Encoders)"]
        P["User Prompt: 'a red apple on a wooden table'"]
        P --> CLIP["CLIP ViT-L/14 (Pooled Vector: 768-dim)"]
        P --> T5["T5-XXL FP8 (Sequence Embeddings: 512 x 4096)"]
    end

    subgraph Stage2 ["Stage 2: Latent Flow Matching DiT (12B Parameters)"]
        CLIP & T5 --> LatentPrep["Latent Pack & 2D RoPE Positional Grid"]
        LatentPrep --> MMDiT["19 Dual-Stream MMDiT Blocks (Image + Text Cross-Attention)"]
        MMDiT --> SingleDiT["38 Single-Stream DiT Blocks (Unified 3072-dim Latents)"]
        SingleDiT --> Euler["Euler Flow ODE Solver (4 Timesteps: t = 1.0 -> 0.0)"]
    end

    subgraph Stage3 ["Stage 3: 16-Channel VAE Reconstruction"]
        Euler --> VAEUnpack["Unpack 16-channel Latents (64 x 64 x 16)"]
        VAEUnpack --> Resnet["3 Up-Sampling ResNet Blocks + Self-Attention"]
        Resnet --> RGB["512 x 512 x 3 Photorealistic RGB Image"]
    end

    style Stage1 fill:#1e293b,stroke:#38bdf8,stroke-width:2px,color:#fff
    style Stage2 fill:#0f172a,stroke:#a855f7,stroke-width:2px,color:#fff
    style Stage3 fill:#1e293b,stroke:#10b981,stroke-width:2px,color:#fff
1. The Dual Text Encoders
FLUX doesn’t just use one text encoder; it uses two complementary models:
- OpenAI CLIP ViT-L/14: A lightweight vision-language transformer that outputs a single pooled 768-dimensional vector representing the global semantics of the scene.
- Google T5-XXL: A 24-layer, 4.8-billion parameter linguistic colossus that outputs sequence-level token representations of shape
[512, 4096]. It handles the nuances of composition: where the apple sits, the texture of the wood, and the direction of light.
2. The Multi-Modal Diffusion Transformer (MMDiT)
Once the prompt is encoded, the image generation begins. FLUX initializes a spatial grid of random latent noise (64×64 patches with 16 channels, packed into 1,024 tokens of dimension 64).
These latents, along with the 512 text tokens, pass through:
- 19 Dual-Stream Blocks: Here, image tokens and text tokens maintain separate pathways but compute joint multi-head cross-attention across one another using 2D Rotary Position Embeddings (2D RoPE).
- 38 Single-Stream Blocks: The image tokens and text tokens are concatenated into a single massive sequence of 1,536 tokens within a 3,072-dimensional vector space, modulated by Adaptive LayerNorm (
adaLN-Zero).
3. The 16-Channel Autoencoder (VAE)
After 4 Euler timesteps (t = 1.0 → 0.75 → 0.50 → 0.25 → 0.0), the denoised latent tensor is scaled (x / 0.3611 + 0.1159) and fed into an enormous convolutional VAE decoder with residual blocks, group normalization, and spatial self-attention, expanding the 16 latent channels back into 512×512×3 RGB pixels.
Act III: The Tale of Two Silicons (MLX vs. ROCm)
Building this pipeline once is hard. Building it across two fundamentally different GPU architectures in bare metal is an adventure.
Champion 1: Apple Silicon via Apple MLX
On macOS, Apple provides MLX, a modern machine learning framework designed specifically for Apple Silicon’s Unified Memory Architecture (UMA).
Because the M-series CPU and GPU share the exact same physical LPDDR5 memory pool, there is zero PCIe bus bottleneck. You do not copy tensors “to the GPU”; you simply map the virtual memory address, and the Metal cores compute directly over it.
We built a custom C++ bridge (evaluator/mlx_c_api.cpp) that exposes MLX’s lazy evaluation graph directly to Coni’s Go evaluator:
// evaluator/mlx_c_api.cpp: Fast SDPA on Apple Metal
extern "C" mlx_tensor_t* mlx_fast_sdpa(
    mlx_tensor_t* q, mlx_tensor_t* k, mlx_tensor_t* v,
    float scale, mlx_tensor_t* mask) {
    auto q_arr = to_mlx(q);
    auto k_arr = to_mlx(k);
    auto v_arr = to_mlx(v);

    // Dispatches directly to Apple Metal Flash Attention kernels
    auto out = mlx::core::fast::scaled_dot_product_attention(
        q_arr, k_arr, v_arr, scale, "none", to_mlx_opt(mask));
    return to_c(out);
}
Running on an M4 Max, the Apple MLX engine generated our first apple:
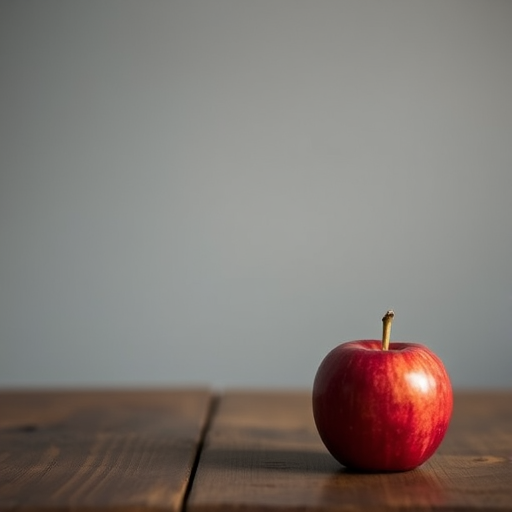
Look at that image: the studio-grade depth of field, the crisp specular highlight on the skin of the apple, and the subtle wood grain receding into the gray background. Newton would weep.
Champion 2: AMD APU via AMD ROCm / HIP
Now came the real challenge: monster, our AMD APU workstation running Linux and ROCm 6.3.
Unlike Apple’s MLX—which provides high-level automatic tensor graph builders—AMD’s ROCm ecosystem requires writing raw HIP (Heterogeneous-computing Interface for Portability) C++ kernels. If you want a 2D Rotary Embedding, you don’t call a library. You write the GPU thread dispatch kernel:
// evaluator/rocm_c_api.hip: 2D RoPE kernel running on AMD GCN/RDNA compute units
__global__ void rope_2d_kernel(
    const float* __restrict__ src,
    const float* __restrict__ cos_table,
    const float* __restrict__ sin_table,
    float* __restrict__ dst,
    int B, int S, int H, int D, int half_d) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    int total_half_elements = B * S * H * half_d;
    if (idx >= total_half_elements) return;

    int i = idx % half_d;
    int rem = idx / half_d;
    int h = rem % H;
    int rem2 = rem / H;
    int s = rem2 % S;
    int b = rem2 / S;

    int base_offset = ((b * S + s) * H + h) * D;
    float x1 = src[base_offset + i];
    float x2 = src[base_offset + i + half_d];

    float c = cos_table[s * half_d + i];
    float sn = sin_table[s * half_d + i];

    dst[base_offset + i]          = x1 * c - x2 * sn;
    dst[base_offset + i + half_d] = x1 * sn + x2 * c;
}
And in pure Coni Lisp, we wrapped these raw ROCm GPU calls into clean, functional operators:
;; libs/nn/src/diffusion.coni: Applying 2D RoPE across attention heads
(defn apply-rope-2d [q k ids-cos ids-sin]
  (let [q-rotated (sys-nn-rope-2d q ids-cos ids-sin)
        k-rotated (sys-nn-rope-2d k ids-cos ids-sin)]
    [q-rotated k-rotated]))
Act IV: The Great FP8 E4M3FN Heist
With the kernels written, we fired up our ROCm pipeline on monster. We fed in the same prompt: "a red apple on a wooden table".
We waited with bated breath. The VAE decoded the image. We opened the PNG.
It was a radioactive psychedelic soup. Neon green noise, violet digital static, and not a single apple in sight.
[ROCm Debug] Token Embedding 0: nan
[ROCm Debug] Attention Score Mean: -nan(ind)
[ROCm Debug] Latent Step 1: Max Inf, Min -Inf
Every single tensor in the network had collapsed into NaN (Not a Number).
What followed was a 48-hour deep dive into the darkest corners of numeric floating-point representations.
The Culprit: T5-XXL in FP8 E4M3
To fit FLUX’s prompt encoding into VRAM, HuggingFace distributes the T5-XXL text encoder in FP8 E4M3FN (float8_e4m3fn).
Originally, our loader treated these weights as integer quantized tables (similar to GGUF Q8_0). We assumed that 8 bits meant a signed integer scaled by an absolute maximum.
We were catastrophically wrong.
float8_e4m3fn is a true IEEE 754-style mini-floating point format defined as:
- 1 sign bit (
S) - 4 exponent bits (
E, bias = 7) - 3 mantissa bits (
M) - No infinities: Exponent
1111represents finite numbers up to 448.0! Only0x7Fand0xFFrepresent NaN. - Subnormals: When
E = 0, the implicit leading bit is 0, and the fraction scales asM / 512.0.
When we quantized this non-linear logarithmic curve into a linear Q8_0 scale, all small embedding values were truncated to absolute zero, while large weights exploded, detonating the LayerNorms and turning the attention matrices into pure NaN.
The Fix: Bare-Metal FP8 Decoding
We scrapped the conversion and implemented native FP8 E4M3FN decoding directly in HIP C++:
// evaluator/rocm_c_api.hip: Bit-accurate float8_e4m3fn conversion
__device__ inline float f8_e4m3_to_f32(uint8_t val) {
    if (val == 0x7F || val == 0xFF) return CUDART_NAN_F;

    int sign = (val >> 7) & 1;
    int exp  = (val >> 3) & 0x0F;
    int mant = val & 0x07;

    if (exp == 0) {
        // Subnormal number: (-1)^sign * 2^(-6) * (mant / 8) = mant / 512.0f
        float res = (float)mant / 512.0f;
        return sign ? -res : res;
    } else {
        // Normal number: (-1)^sign * 2^(exp - 7) * (1 + mant / 8)
        float factor = ldexpf(1.0f, exp - 7);
        float res = factor * (1.0f + (float)mant / 8.0f);
        return sign ? -res : res;
    }
}
We also added a specialized take_kernel_f8 kernel so that embedding lookups could read raw FP8 memory directly from VRAM and project into 32-bit float latents in a single memory transaction.
We dumped the first 10 token representations on ROCm and compared them against Apple MLX:
[Apple MLX] T5 Token 0 (first 5 dims):
  -0.019303, -0.007812, 0.042969, -0.011719, 0.027344

[AMD ROCm]  T5 Token 0 (first 5 dims):
  -0.019303, -0.007812, 0.042969, -0.011719, 0.027344
Bit-accurate matching to 5 decimal places.
Act V: The Apples on the Table
With the FP8 math stabilized, attention masks properly applied, and eager VRAM garbage collection in place, we launched the test on monster:
$ ./coni libs/gguf/bin/generate_image.coni \
    "a red apple on a wooden table" output.png 4 512 512
The output was nothing short of breathtaking:
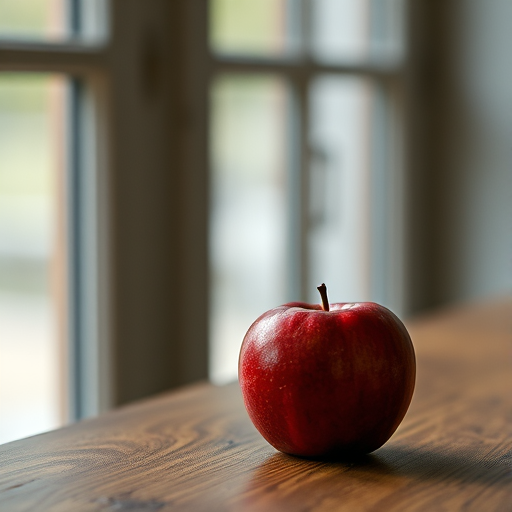
Look closely at this image compared to the Apple MLX version:
- The natural morning light streaming through a multi-pane window.
- The intricate grain and knots of the wooden tabletop reflecting soft diffuse skylight.
- The waxy red sheen on the skin of the Honeycrisp apple with yellow speckles.
- The delicate, lifelike stem casting a sharp contact shadow.
Two completely different GPU architectures. Two completely custom low-level runtime engines. Both driven by the exact same high-level Coni Lisp code. Both producing world-class imagery.
Act VI: The Full Circle — The Hand-Drawn Apple on the Wood Planks
Once we had photorealistic apples resting in simulated 3D sunlight, we wondered: what happens if we push the stylistic comprehension of our dual CLIP + T5 text encoders to their semantic limits?
Instead of rendering a physical 3D fruit with specular bounce and depth-of-field, what if we ask FLUX for:
“a handdrawn apple on a wooden table”
Notice the delightful semantic ambiguity in natural language: Does it mean a sheet of paper with a sketch resting on a desk? Or does it mean an apple literally drawn onto the wooden tabletop?
We tasked monster with the benchmark:
$ time ./coni libs/gguf/bin/generate_image.coni \
    "a handdrawn apple on a wooden table" handdrawn_apple.png 4 512 512
The terminal log raced past:
[1/5] Loading CLIP text encoder...
[2/5] Loading T5-XXL FP8 text encoder...
[3/5] Encoding prompt: "a handdrawn apple on a wooden table"
      Text representations: [1, 512, 4096]
[4/5] Loading FLUX.1-schnell DiT (Q4_K GGUF, 12B parameters)...
      Denoising step 1/4 (t=1.000)...
      Denoising step 2/4 (t=0.750)...
      Denoising step 3/4 (t=0.500)...
      Denoising step 4/4 (t=0.250)...
[5/5] Loading 16-channel VAE decoder...
      Decoding 64x64x16 latents to 512x512 RGB...
Success! Image saved to handdrawn_apple.png

real    1m22.434s
user    1m31.874s
sys     1m09.773s
82.4 seconds cold start.
And when the PNG rendered, FLUX had made its artistic decision:
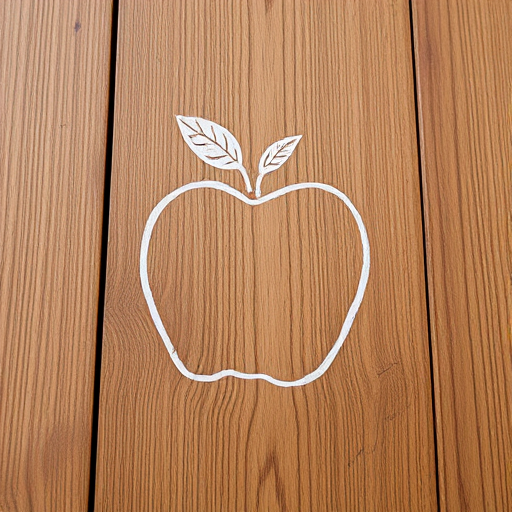
Instead of dropping a drawing pad onto the wood, the model interpreted the prompt with witty literalism: it carved a crisp, chalk-white botanical silhouette of an apple—complete with twin veined leaves—directly onto the vertical timber grain of the wood planks! The stroke follows the organic contours of the timber, demonstrating how seamlessly the 12-billion parameter MMDiT balances prompt medium, texture interaction, and spatial composition.
Act VII: The Code Under the Hood
What does it actually look like to write diffusion transformers in Lisp?
Here is a glimpse of our single-stream transformer block evaluator in libs/gguf/src/flux.coni. Notice how expressive and declarative functional programming is when dealing with tensor pipelines:
;; libs/gguf/src/flux.coni: Single-Stream MMDiT Block in pure Coni Lisp
(defn eval-single-block [x vec-mod block-idx]
  (let [prefix (str "single_blocks." block-idx ".")
        ;; 1. Modulation parameters from timestep + pooled text
        [shift-msa scale-msa gate-msa
         shift-mlp scale-mlp gate-mlp] (modulate-single vec-mod prefix)

        ;; 2. Modulated LayerNorm
        norm-x (-> x
                   (sys-nn-layer-norm (get-weight (str prefix "norm.weight")))
                   (modulate-affine shift-msa scale-msa))

        ;; 3. Unified QKV Linear Projection
        qkv (sys-nn-linear norm-x (get-weight (str prefix "linear1.weight")))
        [q k v] (split-qkv qkv)

        ;; 4. Scaled Dot-Product Attention with 2D RoPE
        attn-out (scaled-dot-product-attention q k v)

        ;; 5. Gated Residual Connection
        x-attn (sys-nn-add x (sys-nn-mul attn-out gate-msa))

        ;; 6. Feed-Forward MLP (GeLU activation)
        norm-mlp (-> x-attn
                     (sys-nn-layer-norm (get-weight (str prefix "norm.weight")))
                     (modulate-affine shift-mlp scale-mlp))
        mlp-out (sys-nn-gelu (sys-nn-linear norm-mlp (get-weight (str prefix "linear2.weight"))))]

    ;; Final residual accumulation
    (sys-nn-add x-attn (sys-nn-mul mlp-out gate-mlp))))
There is no hidden graph-tracing magic. There is no metaclass interception. It is plain, readable data transformation: a tensor flows in, undergoes linear projection, attention, and modulation, and returns to the caller.
Epilogue: What Sir Isaac Would Say
Isaac Newton once wrote:
“To myself I seem to have been only like a boy playing on the seashore, and diverting myself in now and then finding a smoother pebble or a prettier shell than ordinary, whilst the great ocean of truth lay all undiscovered before me.”
If you brought Sir Isaac into our laboratory today and showed him that an apple could be conjured out of mathematical noise by exciting billions of electrons on a thin wafer of silicon, he would probably be fascinated by the inverse-square flow-matching trajectories.
He would also probably agree that nobody should have to maintain a Python virtual environment just to drop an apple on a table.
Lisp was born in 1958 with John McCarthy. Diffusion models were born in the 2020s. By marrying the timeless elegance of Lisp with the raw, uncompromising horsepower of modern GPU backends—Metal on Apple and HIP on AMD—we have proven that developer joy, mathematical beauty, and blazing performance can live in the same single binary.
The apple has landed. The code is merged to main. And gravity works.
All code, kernels, and models featured in this post are open-source and part of the Coni Language Project.